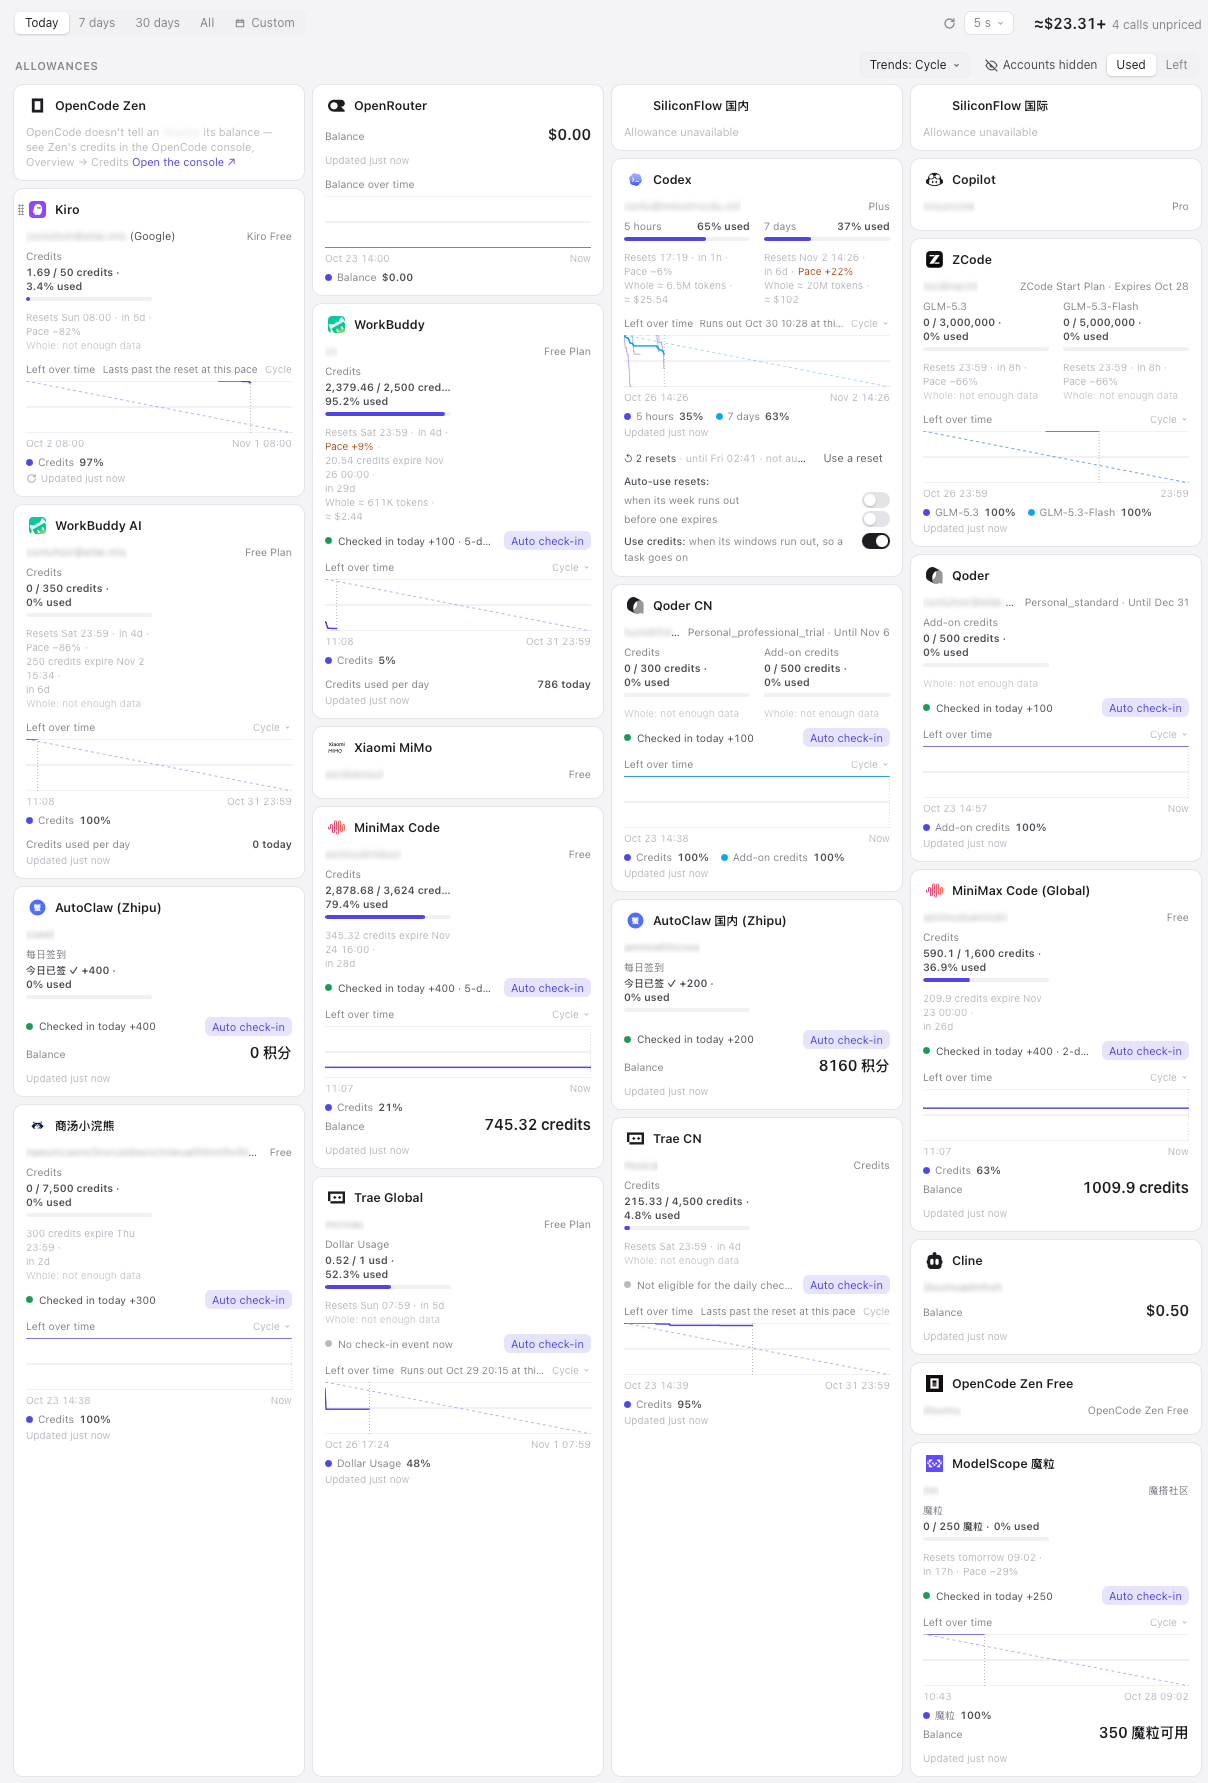
Platforms have been handing out tokens lately: daily check-ins here, promotional credits there. I plug those allowances into OMP + Magpie and put together my own cyber crew.
Codex runs the main session. Free models handle subtasks, digging through code and changing modules in parallel. I'm only on ChatGPT Plus, but I can still run this thing hard and keep it pretty chill. For work, I still lean on Claude Code. Codex has felt a lot dumber lately...
Why OMP + Magpie
OMP (oh-my-pi) is the coding agent I use to work with models. Magpie is a local model gateway that puts accounts, models, and allowances from different platforms behind one endpoint.
| Component | What it handles |
|---|---|
| OMP / Agent Harness | Sessions, tools, context, and subagents; which role uses which model |
| Magpie / Model Gateway | Model access, accounts, and allowances; which provider receives a request |
I chose OMP because its harness fits the way I work. The harness is the tooling, context management, and task orchestration around the model. I still use Codex as the model, with OMP around it. I can configure roles, mix models, and expand the thinking output, tool calls, and status of each subagent.
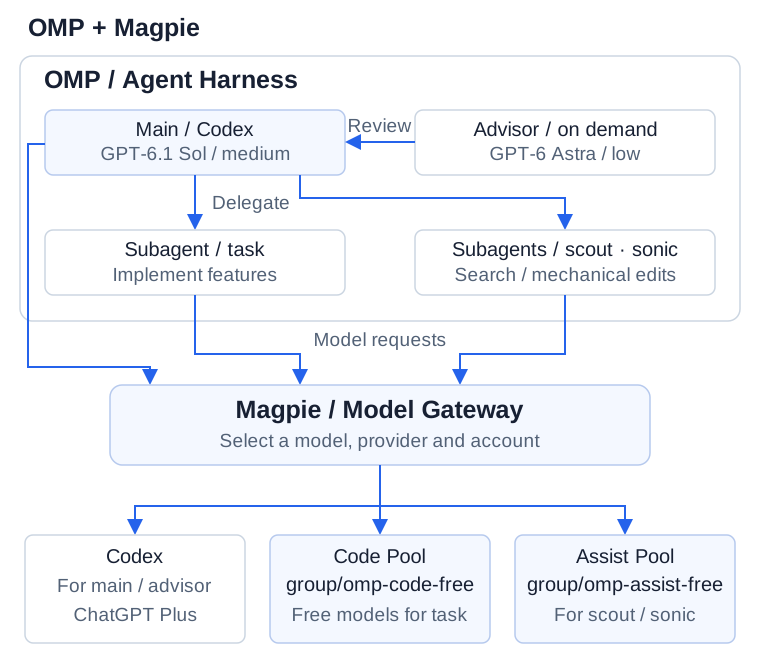
OMP: separate the main session, workers, and reviewer
| OMP Role | Model / Magpie Group | Effort |
|---|---|---|
default / vision / judge |
GPT-6.1 Sol | medium |
advisor |
GPT-6 Astra | low |
task |
omp-code-free |
high |
scout / sonic |
omp-assist-free |
low |
commit / memory / tiny |
omp-assist-free |
low |
My main model is GPT-6.1 Sol / medium. task implements changes, scout searches the code, and sonic handles mechanical edits. I run up to four subagents at once.
The advisor is an extra reviewer, using a separate model to check the main model's work. I want it to catch things the main model missed, so I chose the stronger Astra model. Effort stays at low because Astra burns through too many tokens 😂
I configure the roles in OMP and build the free-model groups in Magpie. The main model delegates, subagents do the work, and the advisor looks for problems.
Magpie: two groups of free models, chosen by task
I split my free models into two groups in Magpie. A group is a list of model endpoints, and I made up the names:
| Magpie Group | Who uses it | Examples: provider / model |
|---|---|---|
omp-code-free |
task, for implementation |
WorkBuddy / DeepSeek V4 Pro; MiniMax Global / M3 |
omp-assist-free |
scout / sonic, for searching code and making small edits |
Groq / GPT-OSS; AutoClaw / GLM Flash |
OMP requests a group such as magpie/group/omp-code-free, and Magpie chooses a model from it. When I add another provider, I add its model endpoint to the appropriate group.
For example, suppose Magpie assigns a code-search subtask to GLM. As that subagent keeps reading files and analyzing code, it tries to stay with the same endpoint. A separate task can go to another model. Several models can work at once without switching providers and rebuilding the prompt cache after every file read.
I give providers with daily check-ins or refreshed allowances a weight of 2; the default is 1, so those providers get more work. A platform gave away a big batch of tokens during the October 24 promotion. I raised its weight for the promotion and set it to revert when the offer expired.
What happens when I ask OMP + Magpie to do something
Say I ask: "Add article search to the blog."
Codex breaks down the work. It asks scout to find where posts are loaded and pages are rendered, then passes the relevant code locations to task for implementation. OMP selects the model group configured for each role. Magpie chooses a free model from that group. When a model needs to read files or edit code, it uses OMP's tools.
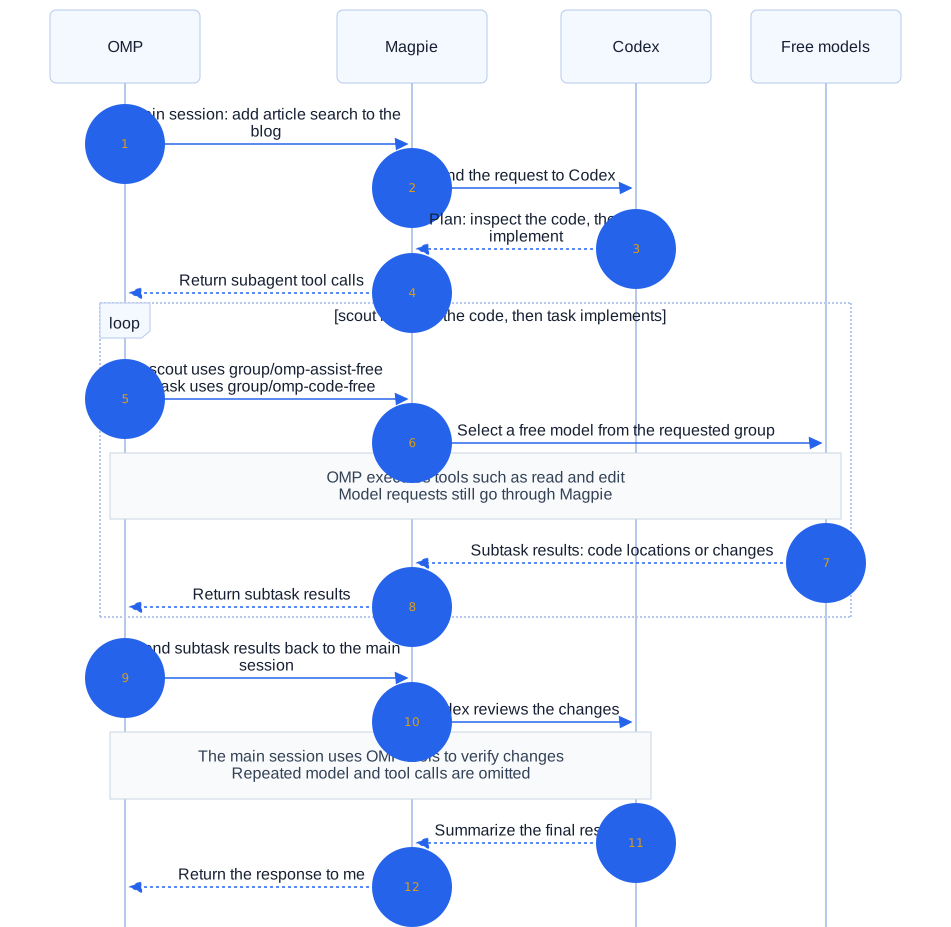
Once the subtasks finish, their results go back to the main Codex session. It reviews the changes, calls tools to verify them, and reports back to me. In OMP, I can watch each subagent work. In Magpie, I can see which model handled a request and how much of the allowance it used.
My finished setup
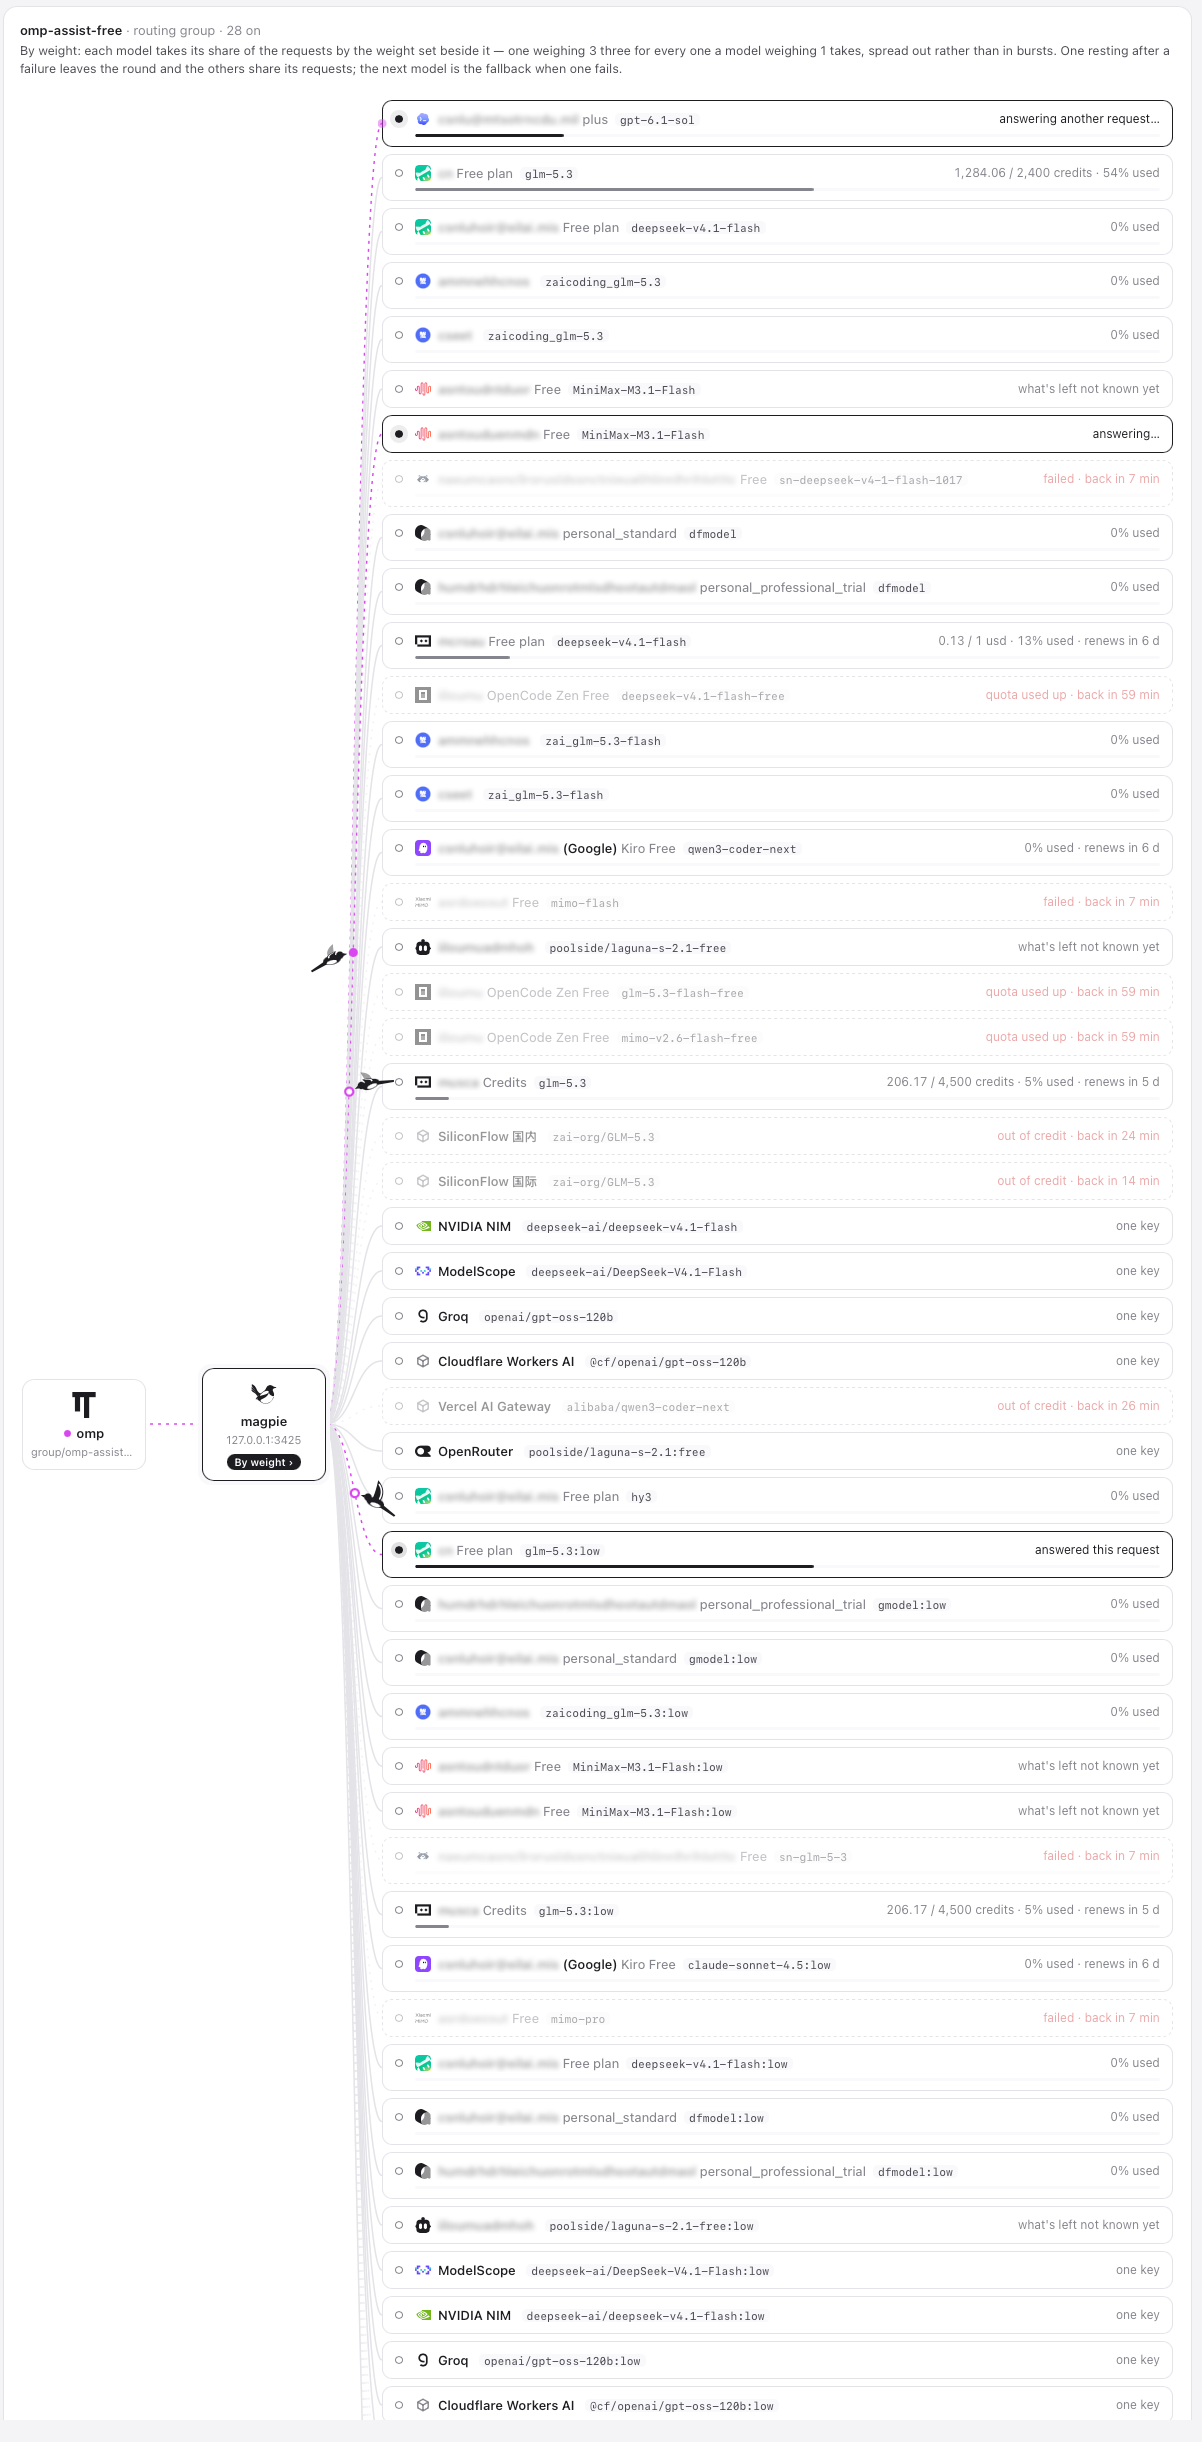
Where I got the tokens
Magpie includes integrations for plenty of providers. I had Codex install Magpie for me and open the signup pages. Once I registered, I had it import the accounts. These are some of the platforms I've signed up for, for reference; I can't promise they still have free allowances. Oh, and Magpie supports automatic check-ins too.